Welcome to ENCODEfetch
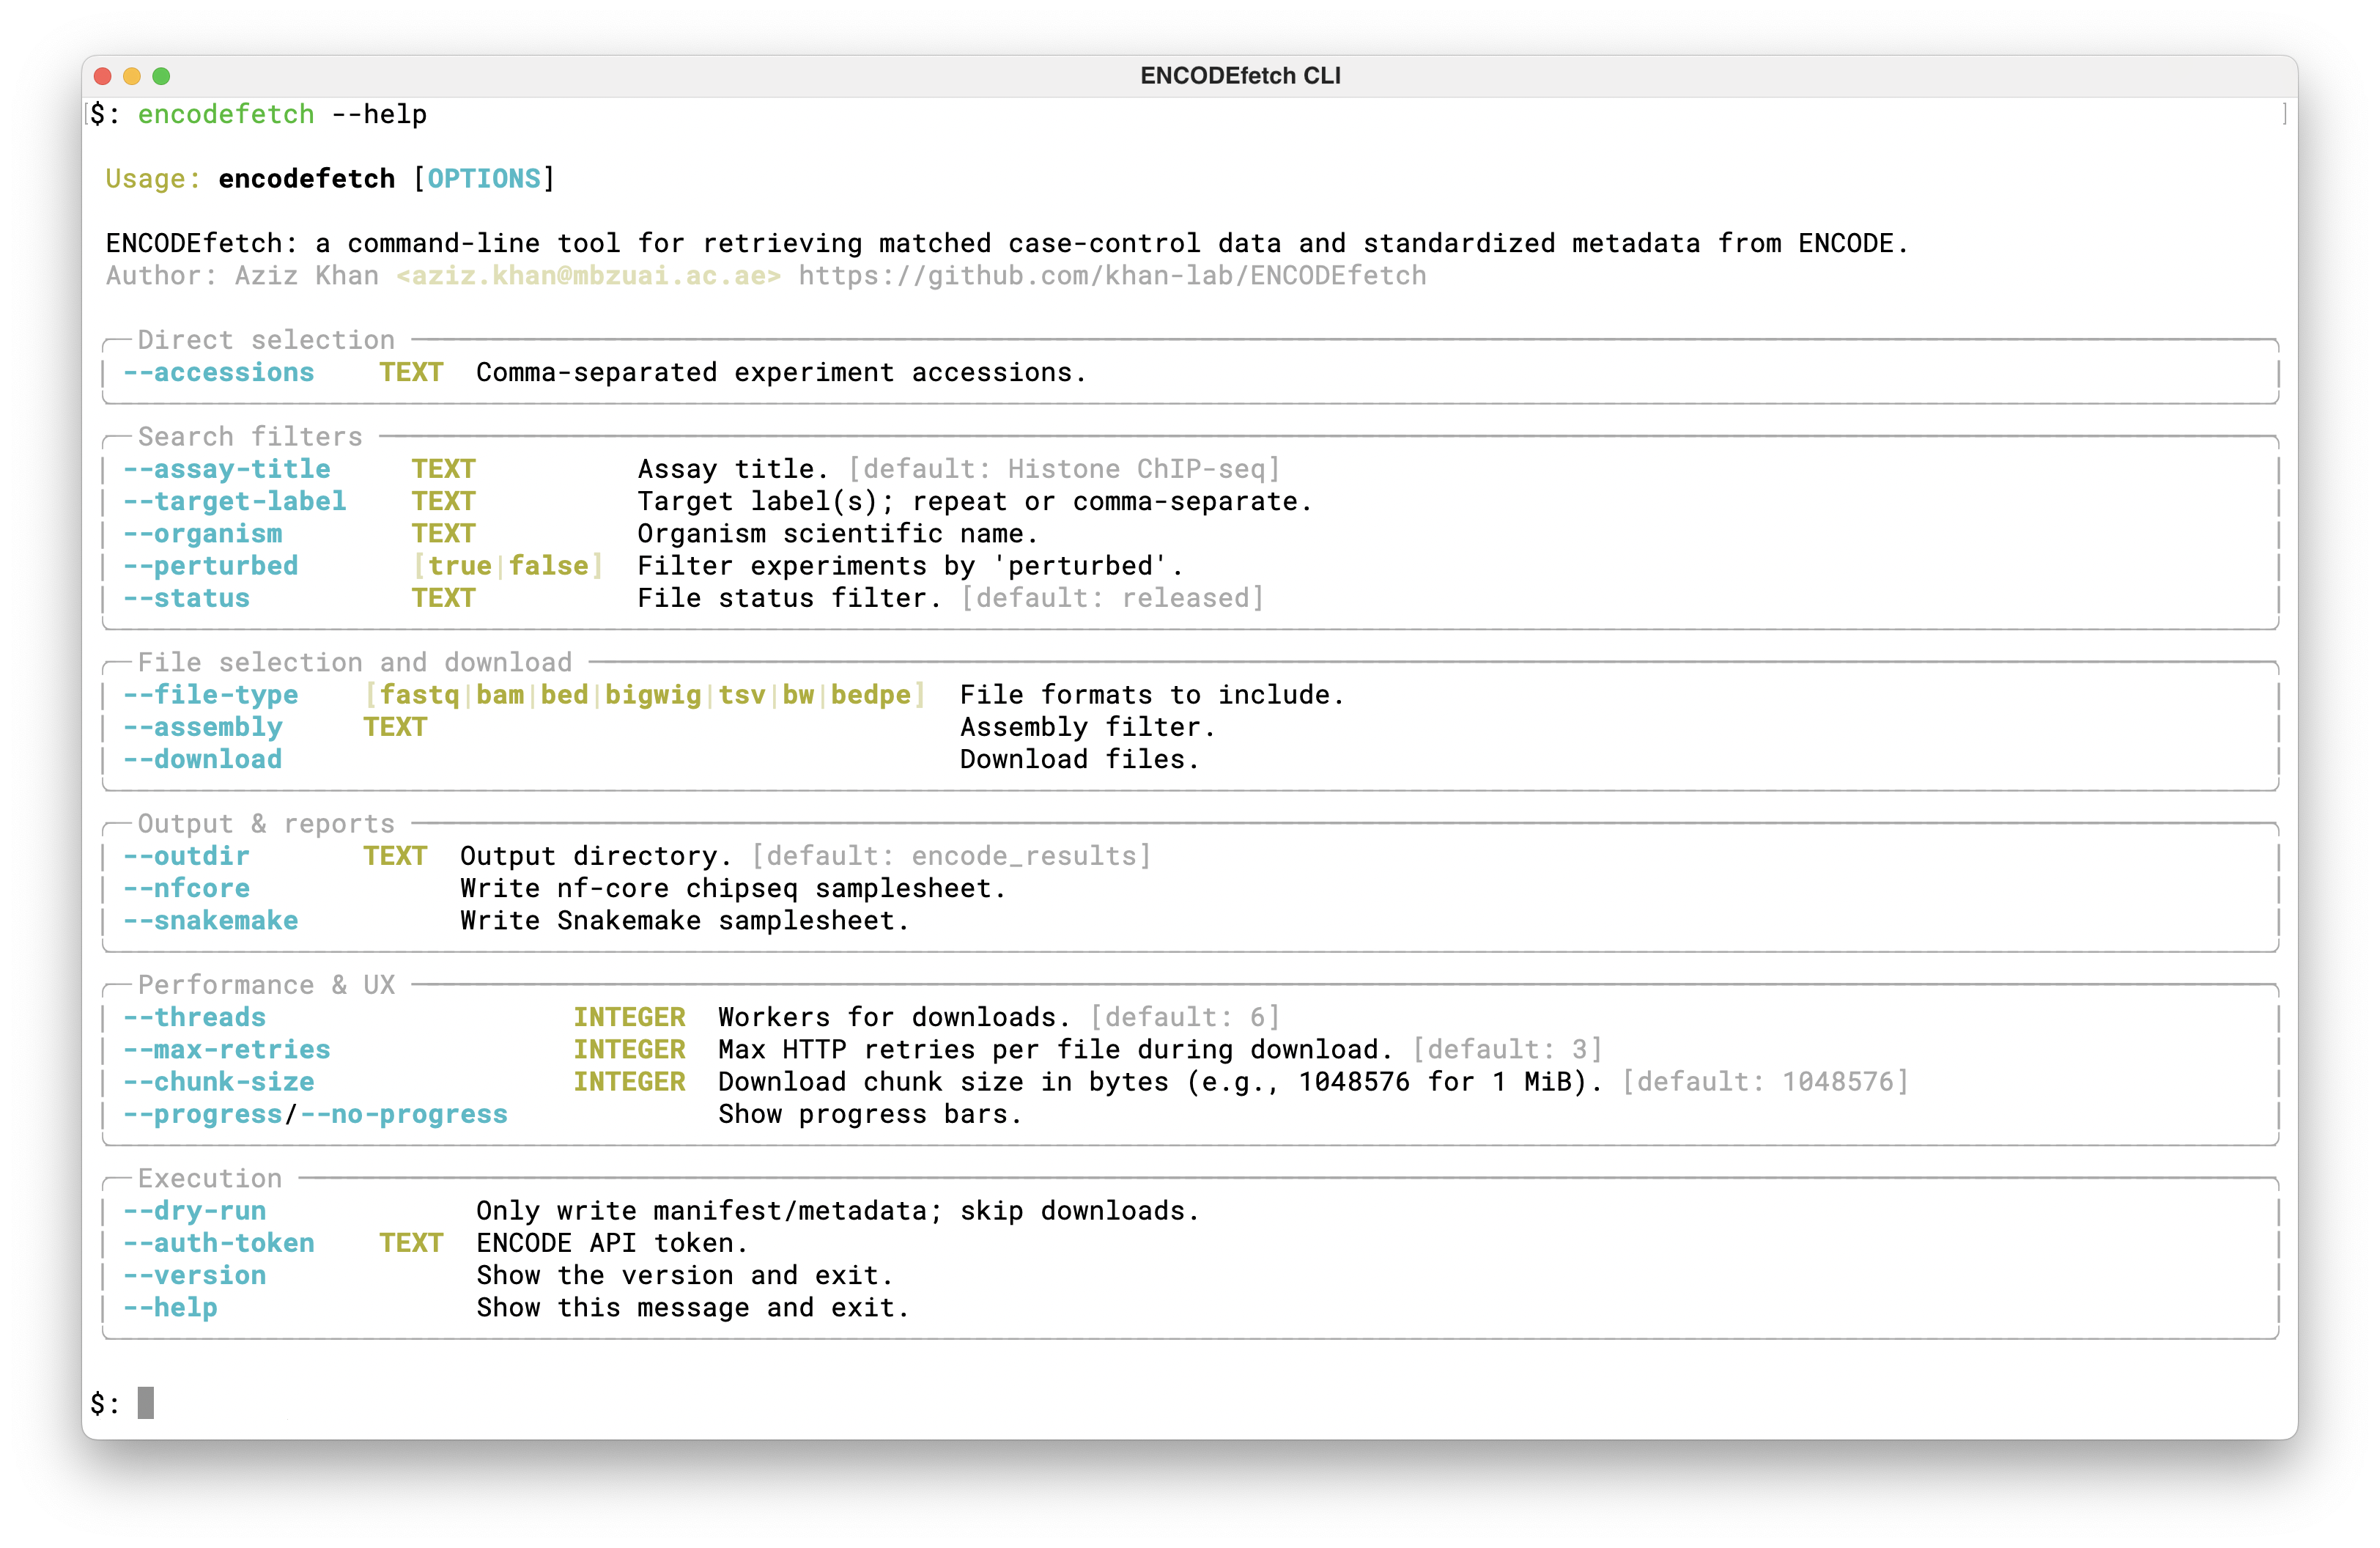
ENCODEfetch is a command-line tool and Python package for retrieving matched case-control datasets and standardized metadata from the ENCODE Project.
It is designed for genomics workflows where you need to search ENCODE, include matched controls, keep a reproducible manifest, and hand the result to downstream pipelines such as nf-core or Snakemake.
Key features
- Search ENCODE experiments by assay, target, organism, biosample, perturbation state, related series, status, file type, and assembly.
- Fetch specific experiment accessions from a comma-separated list or a text file.
- Expand experiment-level
possible_controlsand normalize file-levelcontrolled_bylinks. - Download files in parallel with resumable transfers, retries, chunk-size control, and Rich progress bars.
- Write standardized
manifest.tsvandmetadata.jsonloutputs for auditing and reuse. - Collapse paired-end FASTQs into
fastq_1andfastq_2columns. - Generate samplesheets for nf-core and Snakemake workflows.
- Use the same search and export functionality from Python scripts and notebooks.
Typical workflow
encodefetch \
  --assay-title "TF ChIP-seq" \
  --target-label BRD4 \
  --organism "Homo sapiens" \
  --file-type fastq \
  --status released \
  --metadata-only \
  --nfcore \
  --snakemake
This writes metadata and pipeline samplesheets without downloading FASTQs. Remove --metadata-only when you are ready to download files.
Documentation map
- Installation: install from PyPI or source.
- Quickstart: first complete CLI and Python examples.
- Command Line: all user-facing options and common command patterns.
- Python API: public functions, return values, and notebook use.
- Exporters: nf-core, Nextflow/nf-core, Snakemake, and control strategies.
- Outputs: manifest, metadata, downloaded files, and samplesheet columns.